Pelican Benchmark: Prompt, Examples, and Limits
Try the pelican riding a bicycle SVG prompt, compare AI drawings, and record enough context to make the comparison useful.
Last updated: 2026-09-15
The pelican benchmark asks a language model to write SVG code for a pelican riding a bicycle. It is a quick visual experiment: can the model turn a short description into recognizable shapes and a coherent scene?
The exact prompt
Generate an SVG of a pelican riding a bicycle
Use the same wording for each attempt. Copy the prompt from the gallery, start a new conversation, and save the original SVG response before editing it. An image generator producing a bitmap is a different task; keep those results separate from models writing SVG.
Simon Willison documented this experiment in October 2024 and maintains a public collection of outputs. Our gallery links each historical example to its source. Those examples were collected at different times and are not a controlled test of today's services.
What to look for
Start with visible properties that two people can discuss:
- The bird: a recognizable pelican, including its long beak and pouch.
- The bicycle: two wheels connected by a plausible frame, with a seat and handlebars.
- The interaction: the bird sits on the bicycle; its body and limbs connect sensibly to it.
- The SVG: the output renders, stays inside its canvas, and uses shapes and layers coherently.
Art style is a preference. A prettier drawing does not establish better coding ability. Record observable problems, such as a detached wheel, before giving an overall impression.
Examples to compare
Start with the GPT-4o example to inspect its source, then browse the other historical drawings. Each result page includes share images in several formats. Check the recorded model and source date before treating two outputs as contemporaneous.
Fresh CLI runs: September 15, 2026
We ran the exact prompt 12 times: GPT-5.6 Sol and GPT-6 Astra, low and high reasoning, three attempts per setting. These are fresh independent CLI sessions, not the historical gallery examples. All attempts are included below, in run order, without redrawing the SVGs.
The requested model and effort come from CLI flags, not independent verification of the backend snapshot. Codex CLI 0.154.0 ran in read-only temporary folders, with user configuration and project-document loading disabled. Runtime instructions, skills, and tools remained available, and some attempts called tools. Every run warned that skill descriptions were shortened to fit the context budget. Two runs ran concurrently. This is an observational CLI series, not a tool-free model comparison or evidence of a quality regression.
We extracted SVG from each final response; one response supplied a data URL, which we percent-decoded. PNG previews add white margins to fit the same canvas. The run manifest and original SVGs preserve timestamps, requested settings, hashes, extraction details, and tool counts. No attempts were retried to improve their drawings.
Inspect all 12 attempts and their original SVGs
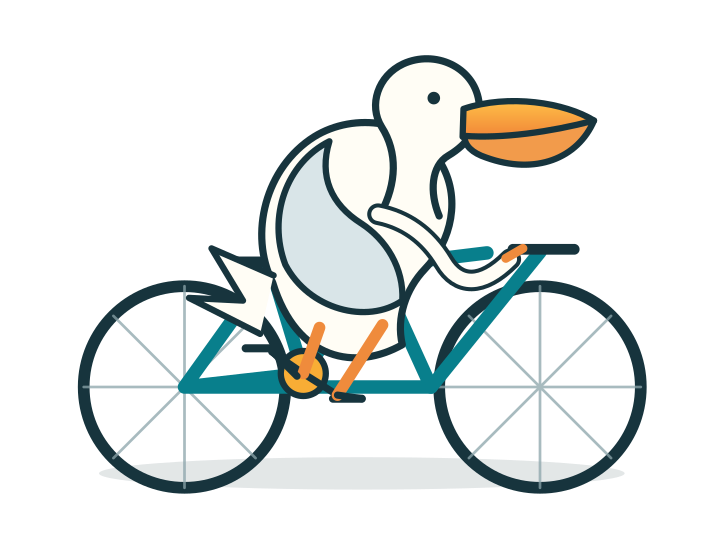
gpt-5.6-sol
low · Run 1
Original SVG
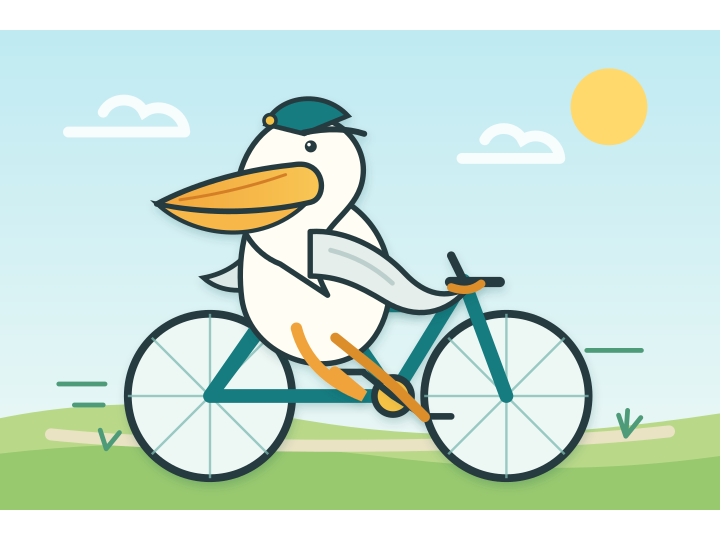
gpt-5.6-sol
high · Run 1
Original SVG
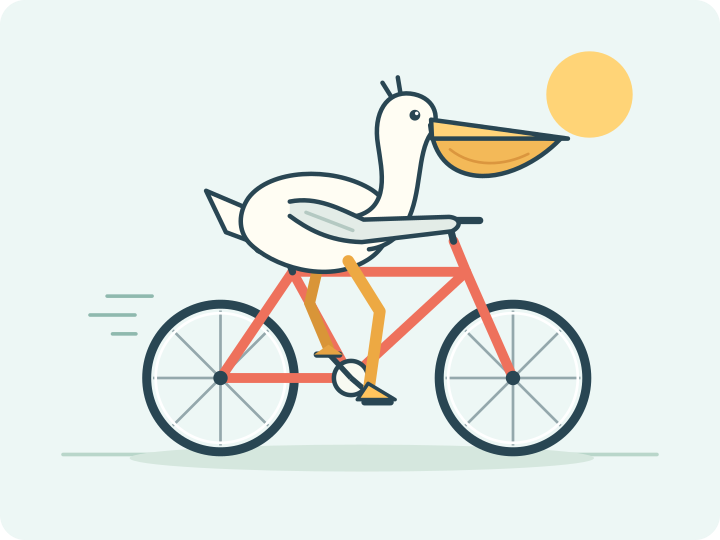
gpt-6-astra
low · Run 1
Original SVG
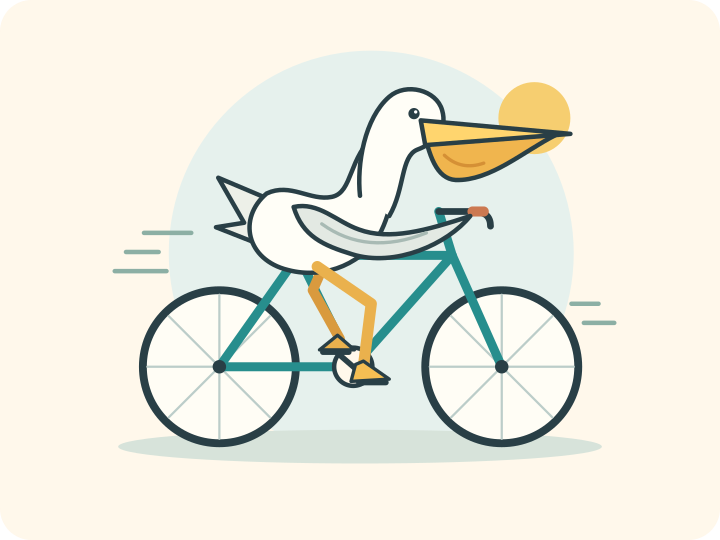
gpt-6-astra
high · Run 1
Original SVG
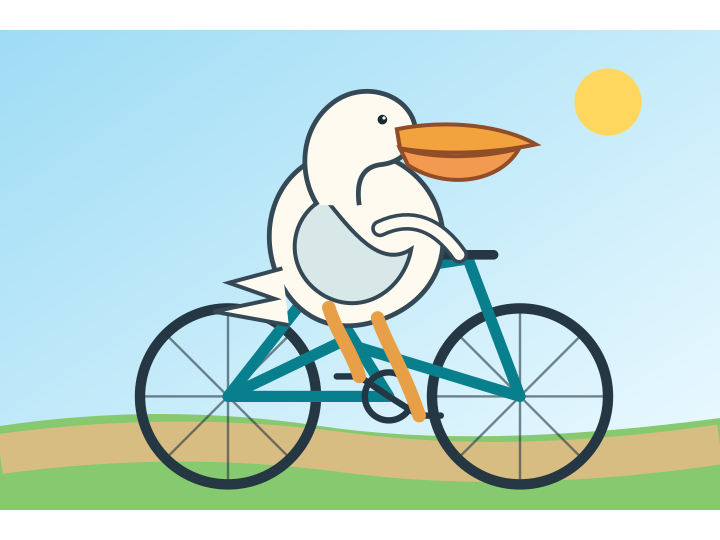
gpt-5.6-sol
low · Run 2
Original SVG
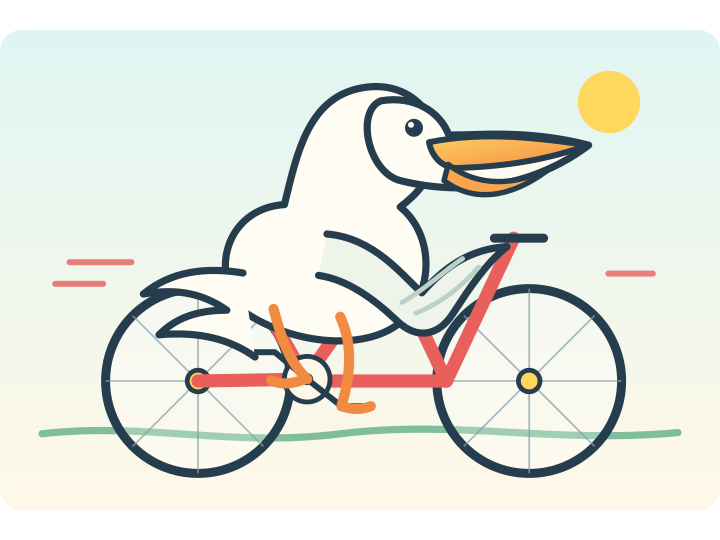
gpt-5.6-sol
high · Run 2
Original SVG
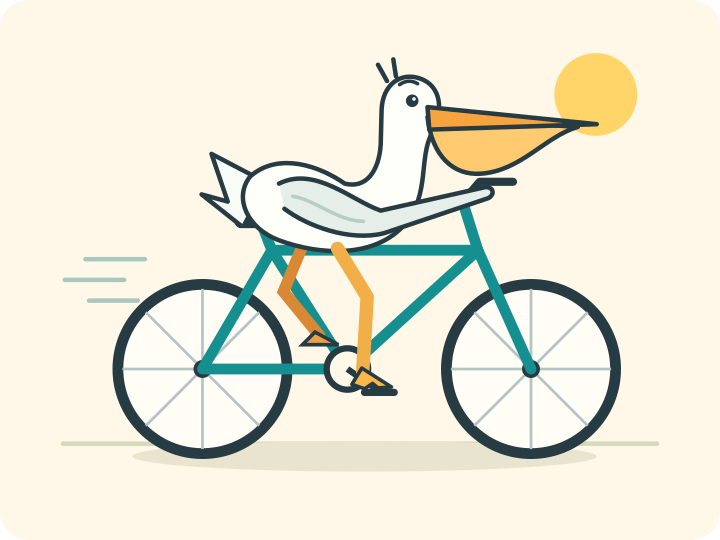
gpt-6-astra
low · Run 2
Original SVG
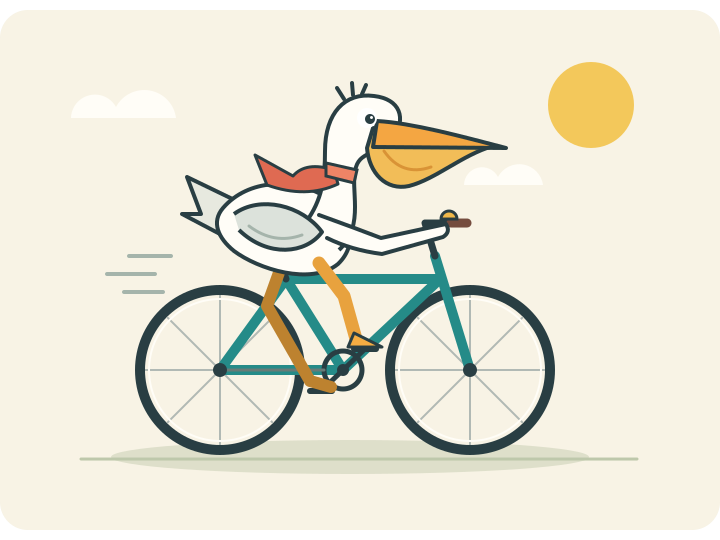
gpt-6-astra
high · Run 2
Original SVG
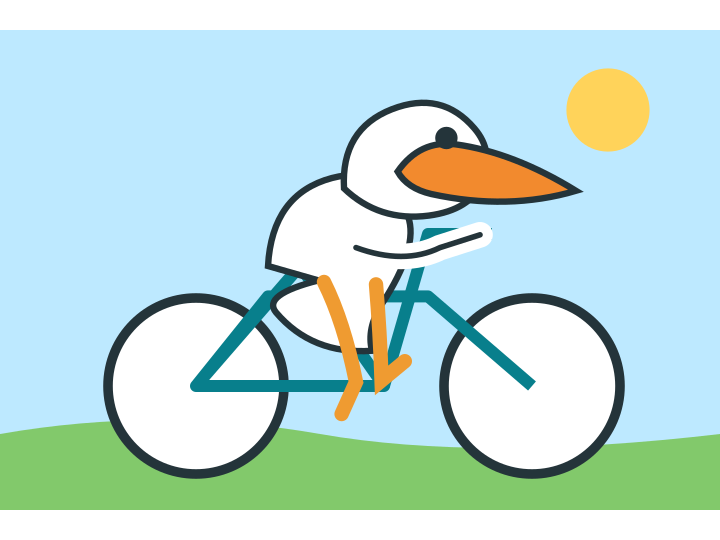
gpt-5.6-sol
low · Run 3
Original SVG
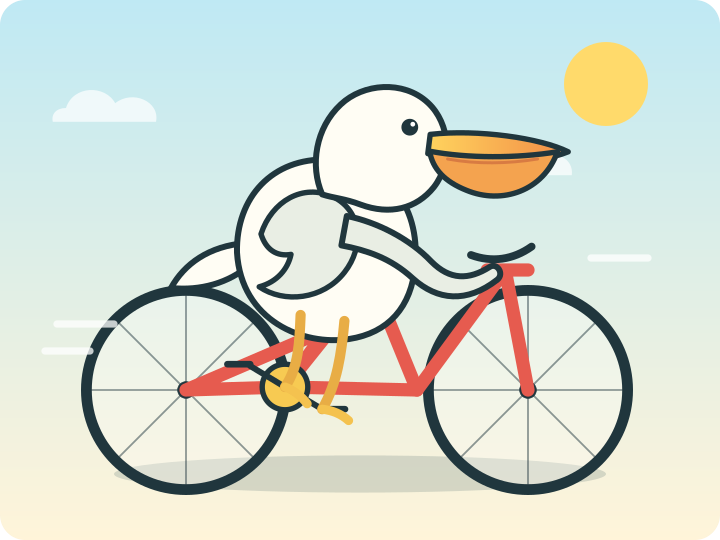
gpt-5.6-sol
high · Run 3
Original SVG
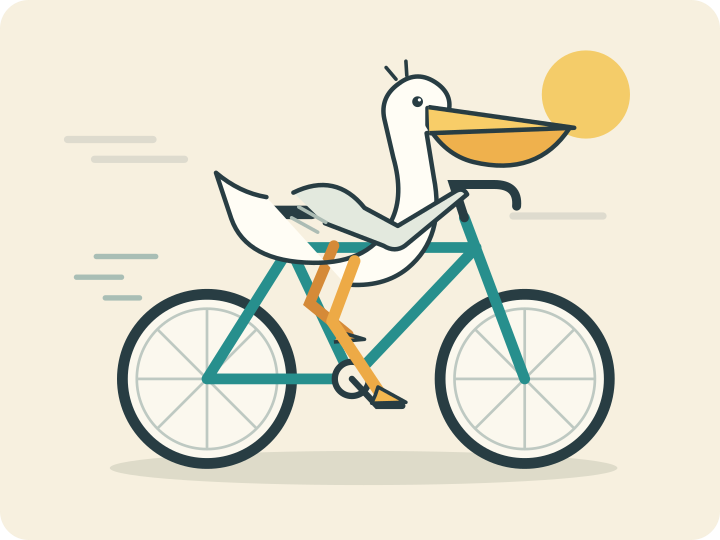
gpt-6-astra
low · Run 3
Original SVG
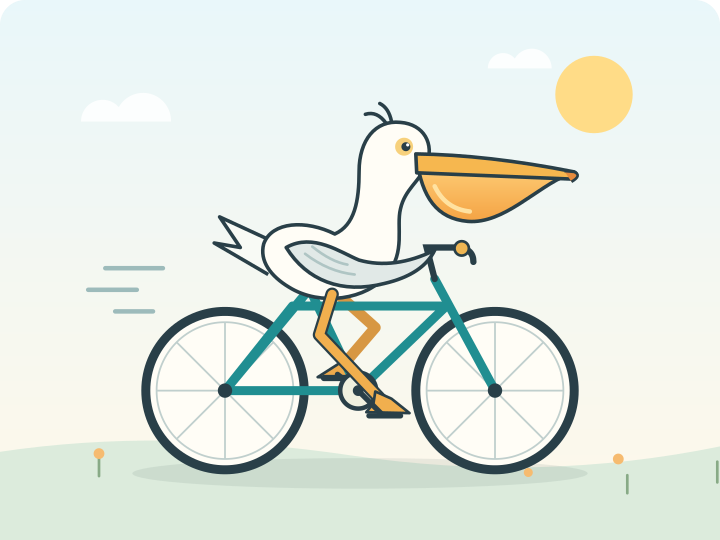
gpt-6-astra
high · Run 3
Original SVG
How to run a fairer comparison
- Choose the model and reasoning effort explicitly. Record the product or CLI version and the date.
- Use fresh conversations with the same prompt, tool access, and instructions. Record any unavoidable differences.
- Run each setting several times. Keep failures and ordinary outputs alongside the best drawing.
- Preserve the raw response. If you extract SVG from a code fence, record that; do not silently repair the model's drawing.
- Separate generation time from visual quality. Network delays and tool use can affect elapsed time.
- If you test revisions, label the result as an iterative attempt and keep the follow-up prompts.
A useful result record includes the requested model, reasoning effort, exact prompt, timestamp, run number, original SVG, and whether you edited or retried it. A model name selected in a client does not independently verify the backend snapshot.
What this benchmark cannot tell you
One drawing cannot prove that Codex has degraded, that a provider changed a model, or that one model is best at software engineering. The prompt is public and widely repeated; familiarity with it can also limit what a good result tells us.
Willison explicitly cautioned against treating a better pelican as general model superiority. His September 2026 Astra comparison also makes reasoning settings part of the experiment. These are reasons to preserve settings and multiple attempts, rather than publish an unexplained ranking.
For a reliability check, use a small task from your own work with known acceptance criteria and repeatable checks. See Codex slow or getting worse? How to check for a diagnostic process.
Share a result with its context
You can submit a drawing with the actual model and prompt. Include reasoning effort and generation date in the text you share alongside it. Community labels are contributor-supplied; publication does not certify the model identity or prove a regression.